GPT-6.1 Terra: How to Test It for Your Business
OpenAI’s GPT-6.1 Terra is a cheaper model for work involving documents, screens and software. Whether it is cheaper for your business depends on the task it completes, the checking it needs and the failures it creates.
OpenAI introduced the model on 26 October 2026. Its announcement reports stronger computer-use and coding results than GPT-5.6 Terra on selected tests. Those are OpenAI’s measurements, not a guarantee for your workflow. Here is how a small team can test the model before giving it real work.
What is GPT-6.1 Terra?
GPT-6.1 Terra is an OpenAI model available through the API and, according to OpenAI’s announcement, in ChatGPT Work and Codex for eligible Plus, Pro, Enterprise and Edu users. Availability and account limits depend on the product and plan. It can analyse text and images and, when connected to an appropriate tool, help an agent interact with software.
That distinction matters. A model provides reasoning and output; a computer-use tool supplies the ability to interact with a screen. An application still needs to define which tools and accounts are available, which actions need approval and how results are checked.
OpenAI describes invoice entry and technical drawings as example tasks. For a small business, the first trial could be simpler: take ten fictional supplier invoices and prepare ten draft records for a person to review. Do not grant payment rights or use real supplier bank details in the first trial.
What does GPT-6.1 Terra cost?
At the standard API rates shown by OpenAI’s pricing page on 28 October 2026, GPT-6.1 Terra costs $1 per million input tokens, $0.05 per million cached input tokens and $5 per million output tokens. GPT-6.1 Sol is listed at $2 input and $10 output per million standard tokens. A token is a unit of text processed by the model; it is not the same thing as a word or a completed task.
These are standard API token rates, not a promise about a ChatGPT subscription invoice. Other service tiers, long inputs, cache writes, regional processing and tools may cost more or be priced differently. Check the current rate and your account’s terms before budgeting.
A simple cost example
Suppose a workflow makes 10,000 API requests. Each uses 2,000 uncached input tokens and 500 output tokens. That is 20 million input tokens and 5 million output tokens.
- Terra: (20 × $1) + (5 × $5) = $45 in model token charges.
- Sol: (20 × $2) + (5 × $10) = $90 at the same token counts.
This is an illustration, not a quote or measured workload. It excludes cached input, tools, retries, setup, hosting, human review and taxes. If Terra needs more attempts or checking to reach the same quality, the complete cost gap may be smaller. A cheaper request is useful only when the resulting work is good enough.
For the wider cost of building and operating an agent, use our AI agent pricing guide. For selecting models per request, see LLM routing; this article focuses on a first buyer test of Terra.
What the benchmarks do and do not tell you
OpenAI reports that, at maximum reasoning effort, Terra solved 50.3% of tasks on Terminal-Bench 4.0, compared with 21.5% for GPT-5.6 Terra. The company also reports a 15-percentage-point improvement over its predecessor on Agents’ Last Exam at medium effort and about one-third the cost on that test. These figures are vendor-reported benchmark results under its stated conditions.
They do not establish that Terra is twice as good on your codebase, that an invoice will be entered correctly or that every task is safe to automate. A benchmark can help select what to test; it cannot replace your own acceptance criteria.
“Compare models on the task you actually need done. Include the time your team spends checking the result and handling the exceptions.”
Bohdan Semenov, Head of Delivery at Powercode Group
Try one task before connecting your business systems
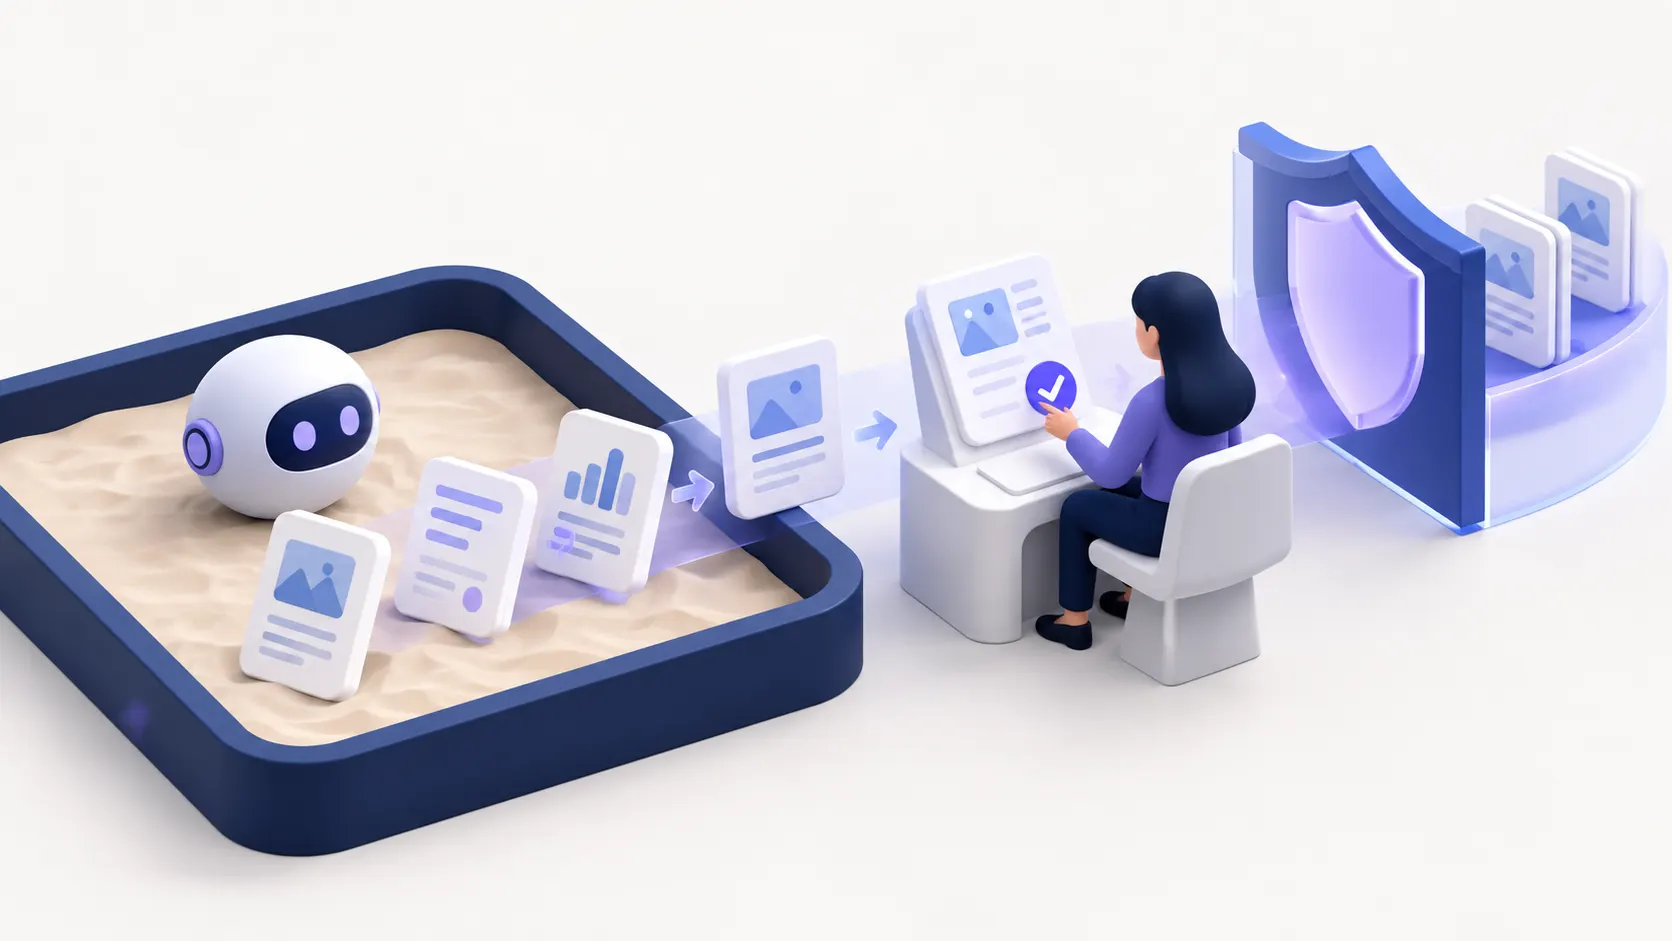
Pick a task that is frequent, easy to grade and reversible. Suitable first candidates include classifying fictional support requests, extracting fields from sample invoices or preparing a draft spreadsheet. Keep sending messages, changing production records, placing orders and making payments outside the initial test.
- Create a small test set. Include normal cases, missing information and a few difficult cases. Use synthetic or approved data.
- Write the answer key. Decide what correct means before running either model. Mark fields where “unknown” is the right answer.
- Run the same task. Compare Terra with your current process or another suitable model using equivalent instructions and access. Record settings, token use and relevant tool charges.
- Score quality and exceptions. Count complete correct results, errors, unsafe actions and cases sent to a person. A partial answer can still require a full review.
- Measure end-to-end effort. Include waiting, correction, retries and the human approval step, not just the model’s response time.
- Decide the next boundary. Continue with drafts, expand a limited test, redesign the workflow or stop. Give any real system only the access needed for the approved task.
Three or ten test cases can expose obvious problems, but they cannot prove a production failure rate. Increase coverage before consequential use and repeat tests when the model, software or instructions change.
What should an AI agent be allowed to do?
Give a test agent its own account and the narrowest practical permissions. Start read-only where possible. Require a separate human approval for an external message, purchase, deletion or change to a live customer record. Keep an activity log and a way to stop or revoke access.
These controls matter even when the model is designed to follow instructions. In its October 2026 report on unintended model actions, Anthropic described cases involving real websites during evaluations and internal use. That is evidence about Anthropic’s reported cases, not a finding that Terra behaved the same way. It illustrates why tool permissions and review should sit outside a model’s own judgment.
For a deeper engineering treatment, read our AI agent security guide and agent evaluation guide. If a workflow needs predictable rules rather than autonomous choices, compare an AI workflow with an AI agent first.
Common questions about GPT-6.1 Terra
Is Terra the cheapest model for every task?
No. Compare the current prices of suitable models and measure the cost of a correct, accepted result. Token price alone does not include retries or review.
Can it enter data into accounting software?
It can be used in a system with an appropriate computer-use tool, subject to access and product capabilities. Begin with a test environment and draft records, and keep a person responsible for approval.
Does a subscription include unlimited API usage?
Do not assume so. ChatGPT Work, Codex and API access have different account and billing rules. Check your plan and the current provider documentation.
Need help turning a pilot into a working process?
Powercode Group can help you add AI engineering capacity or build an application through our custom software development service. Tell us about the task, its inputs, the systems involved and what a successful result must look like. Agree the scope and access before connecting production data.